AI developer productivity: from −19% to +56%, what each study actually measured
AI developer productivity in 2025–2026: what METR, the Microsoft field trials, the Claude Code rollout study, GitClear, DORA and Stack Overflow measured, why they disagree, and how to measure the effect in your own team.
Two published numbers about AI developer productivity are both true: developers finished a task 55.8% faster with GitHub Copilot, and experienced developers took 19% longer with AI tools. They come from different studies that asked different questions: one isolated task in a controlled experiment, and real issues in large codebases the developers knew well.
The cleanest way to settle the question, a randomised trial on real work, stopped producing a reliable number in 2026. In METR’s follow-up, 30–50% of surveyed participants held back some of the tasks where they expected AI to help most. That leaves one source you can fully trust: your own measurement. Below is what each major study measured, where its numbers stop applying, and a measurement plan for your team.
01 · Four numbers, four questions
These results get quoted most in 2025–2026:
- 55.8% faster — researchers from Microsoft, GitHub and MIT (experiment in 2022, paper in 2023): 95 freelance developers with GitHub Copilot wrote an HTTP server in JavaScript 55.8% faster than the control group.
- 26% more completed tasks — three field experiments with GitHub Copilot at Microsoft, Accenture and a Fortune 100 company, 4,867 developers (Management Science). The estimate is 26.08% with wide uncertainty (standard error 10.3 points).
- 24% more merged PRs — Microsoft’s study of its early-2026 rollout of Claude Code and GitHub Copilot CLI across tens of thousands of engineers.
- 19% longer — METR’s randomised trial (2025): 16 experienced open-source developers took 19% longer on real issues when AI was allowed.
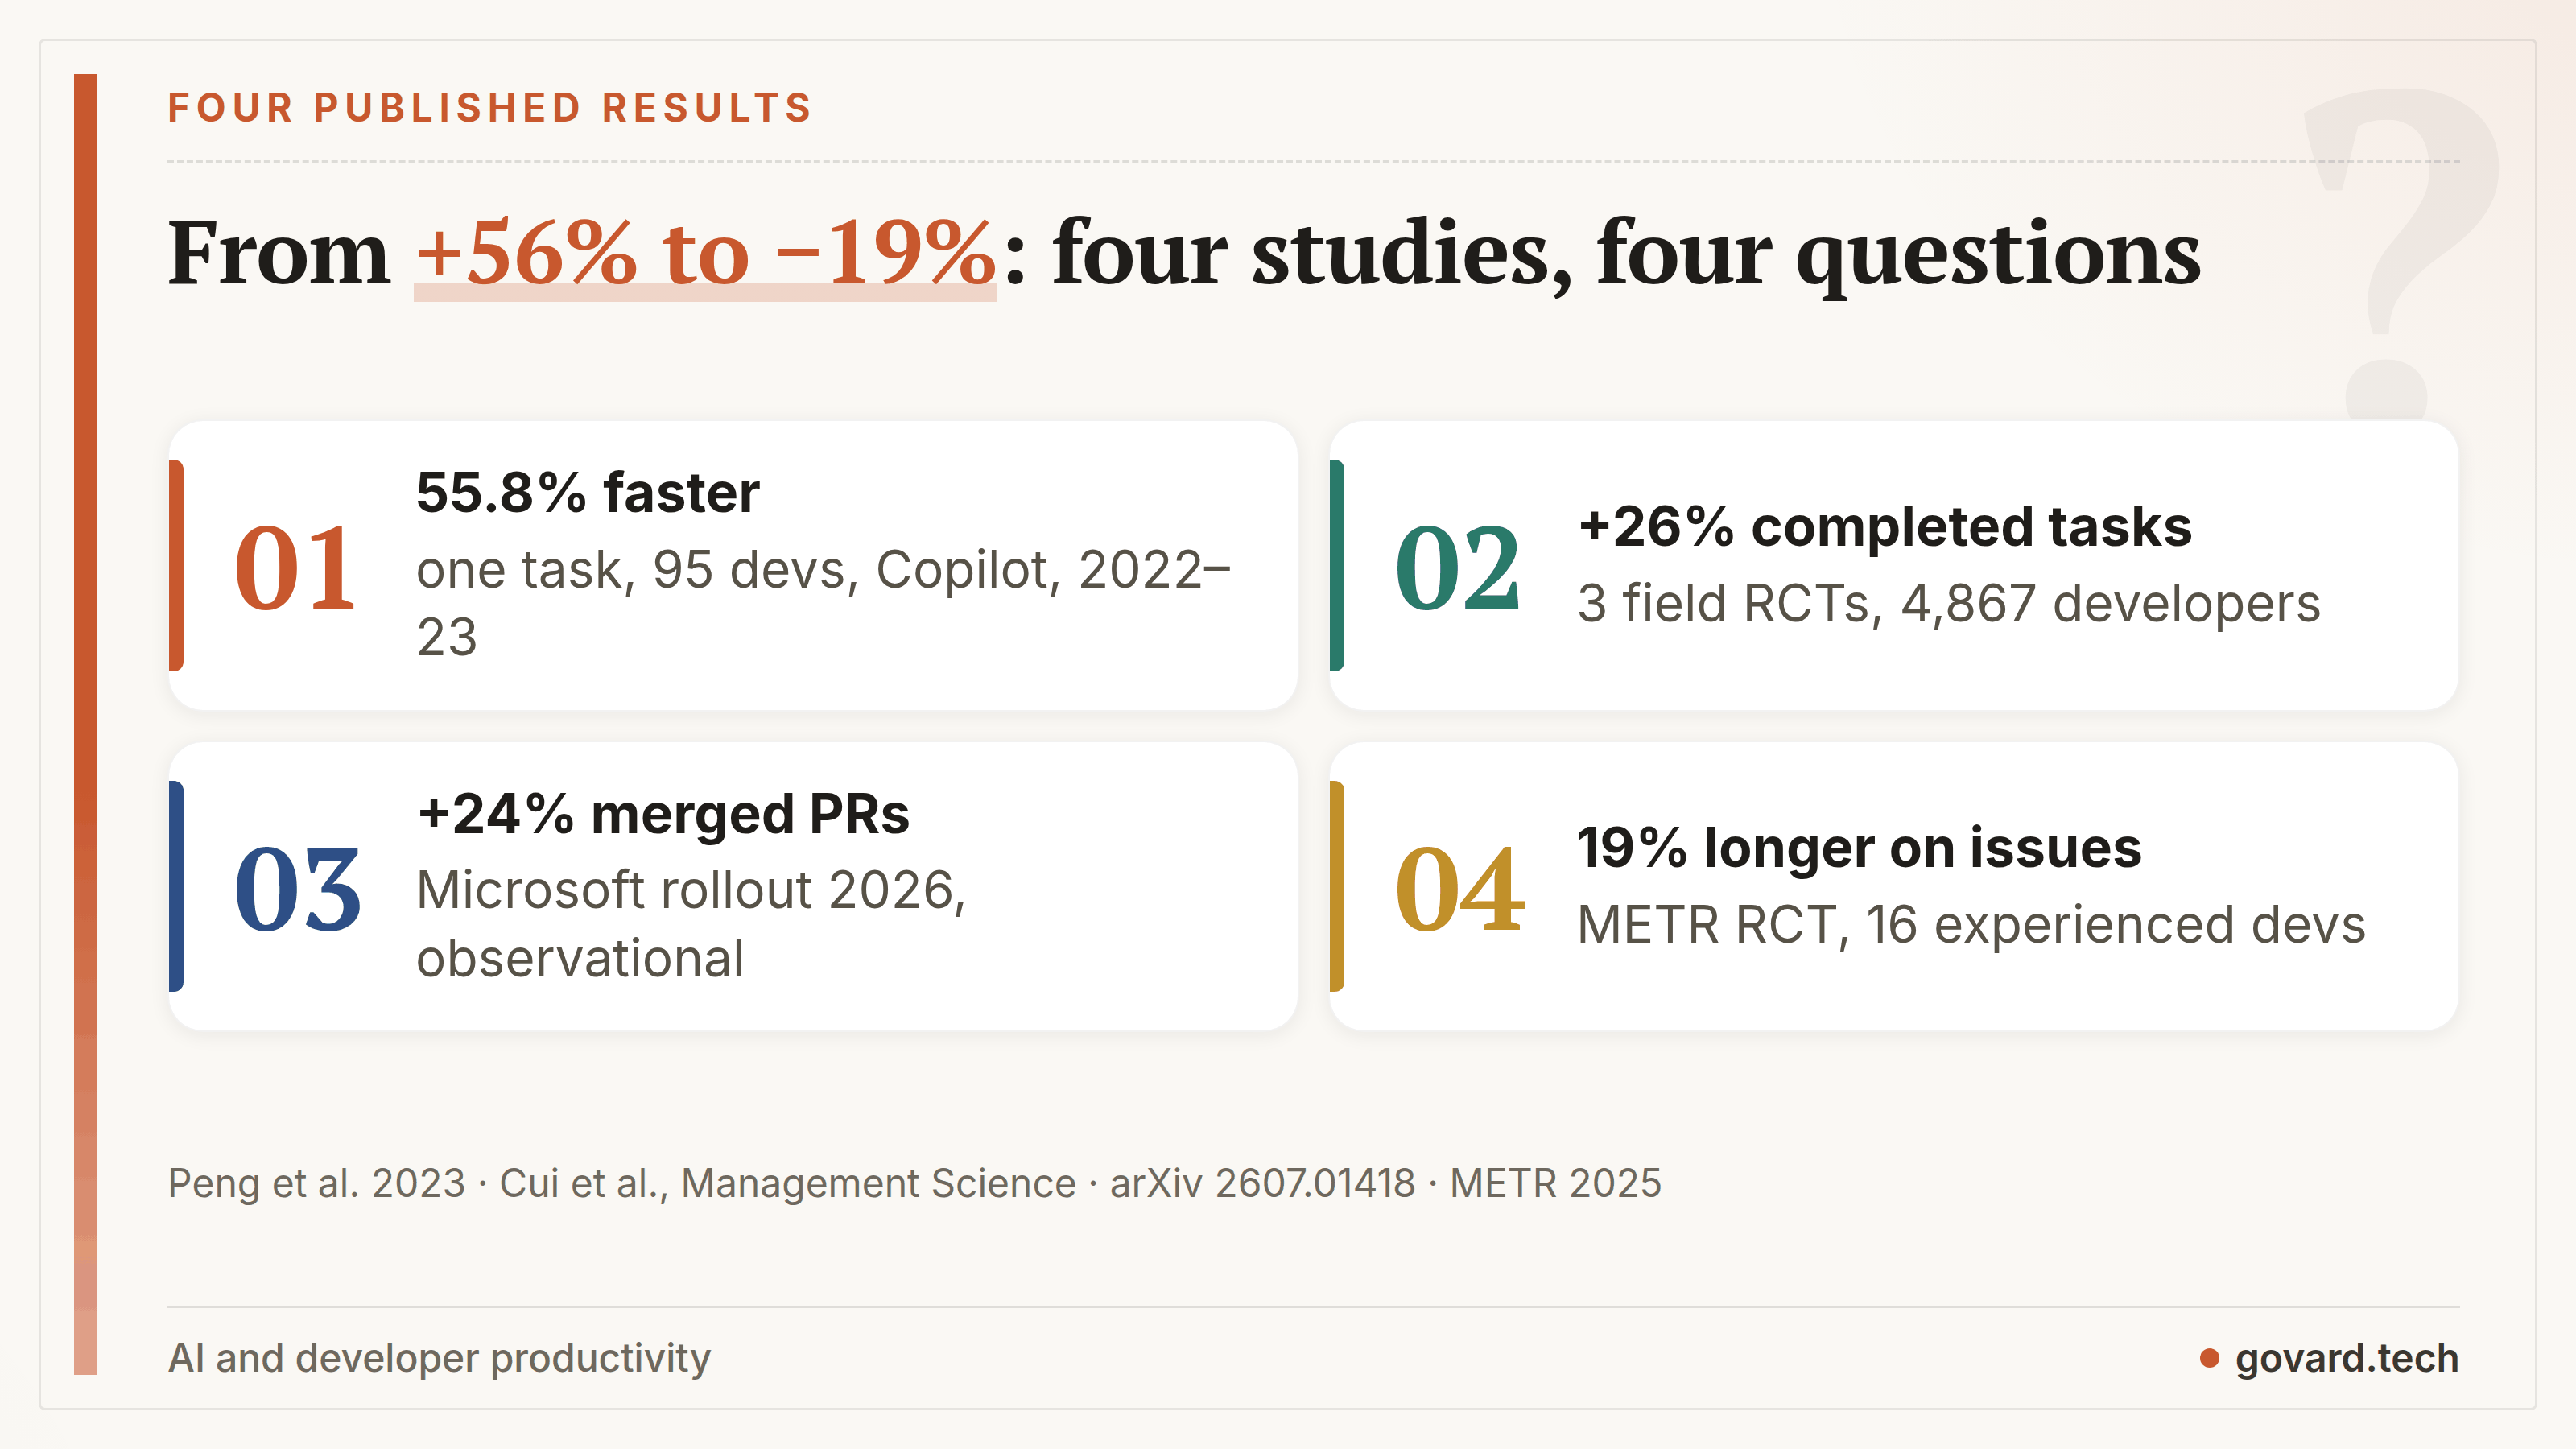
These figures don’t contradict each other because they measure different things. One is time on a single greenfield task, two count output units (tasks, PRs), one is time on hard issues in familiar code.
02 · Not all evidence is equal
Before quoting any of these numbers, check how each was produced. Randomised designs come first, observation and code analysis next, surveys last:
| Study | Design | Sample | Result | What it can tell you |
|---|---|---|---|---|
| Cui et al. | Three field randomised trials, GitHub Copilot | 4,867 developers | +26% completed tasks | Broad; “completed tasks” is an indirect measure |
| METR 2025 | Randomised trial on real issues | 16 developers, 246 tasks | 19% longer | Experienced devs, familiar large repos, early-2025 tools |
| Peng et al. | Controlled experiment, GitHub Copilot | 95 developers, one task | 55.8% faster | Isolated greenfield coding |
| Microsoft 2026 rollout | Observational, no randomisation | Tens of thousands | +24% merged PRs | Adoption effect; a PR is not value |
| GitClear 2026 | Code analysis, not causal | 623M changes | Duplication up, refactoring down | Code health |
| DORA 2025 | Survey + interviews | ~5,000 people | 80%+ feel more productive | Perception |
| Stack Overflow 2025 | Survey | ~49,000 people | 84% use AI, 33% trust its accuracy | Adoption and trust |

The Microsoft authors state the limit of their own number: “a merged PR is not the same as the value it delivers”. Cui et al. and the rollout study also share an institution, so they don’t fully confirm each other independently.
03 · METR: slower, and sure they were faster
METR’s study is the most cited and the narrowest. Sixteen experienced maintainers of large open-source projects (on average 22,000+ stars and over a million lines of code) worked on 246 real issues of about two hours each. Each issue was randomly assigned to “AI allowed” or “AI not allowed”. The tools were mostly Cursor Pro with Claude 3.5 and 3.7.
“When developers are allowed to use AI tools, they take 19% longer to complete issues.” — METR, July 2025
The second finding matters more for anyone running a team. Before the study, developers predicted a 24% speed-up. After finishing the tasks, they still believed AI had made them 20% faster.

METR limits its own conclusion. The authors call the result “a snapshot of early-2025 AI capabilities in one relevant setting”. They allow that AI may help “less experienced developers, or … developers working in an unfamiliar codebase”, and that learning effects may “only appear after several hundred hours of usage”. Participants had a few dozen hours with Cursor.
04 · Why METR’s follow-up gave an unreliable signal
In August 2025 METR started a second experiment with 10 developers from the first study and 47 new ones, and cut pay from $150 to $50 an hour. In February 2026 the team wrote that the new data “gives us an unreliable signal”. One reason was selection: 30–50% of surveyed participants said they held back some tasks they did not want to do without AI. METR describes this as affecting a minority of developers and tasks.
On raw data, returning developers were about 18% faster (confidence interval from 38% faster to 9% slower), and new ones about 4% faster (from 15% faster to 9% slower). Both intervals include zero. METR treats the result as a lower bound and is changing the design.
That failure is a data point too. Within a year, a noticeable share of experienced developers stopped treating “no AI” as an acceptable condition for the tasks where they expect the most help.
METR’s self-report survey (February–April 2026, 349 technical workers) shows the other side: a median 3× self-reported speed-up and a 1.4–2× change in the value of work. METR repeats its own warning from 2025: people “overestimated AI’s effect on their time spent on tasks by 40 percentage points on average”.
05 · What the speed numbers leave out
Speed studies count tasks, PRs or hours. Two other measures change the picture.
Code health. GitClear analysed 623 million code changes from 2023 to 2026. Compared with 2023:
- duplicated code blocks +81%;
- copy-paste within a commit +41%;
- code churn within two weeks +15%;
- moved (refactored) code fell from 13% to 3.8% of changed lines, about −70%; cross-file function calls fell 35%.
GitClear also notes that heavy AI users produce 4–10× more code than non-users, while compared with their own past output the gain is about 25%. A gap between people is not the same as the effect of a tool. GitClear sells code analytics: the counts are objective, and the “maintainability gap” reading is the vendor’s position.

Trust. In Stack Overflow’s 2025 survey, use and trust diverge: 84% use or plan to use AI tools (up from 76%), while trust in their accuracy fell from 43% to 33%, and 46% actively distrust it. DORA 2025: 90% use AI at work, and 30% report little or no trust in AI-generated code, slightly fewer than a year earlier. DORA’s summary is that AI “amplifies what’s already there”: strong engineering practice gets stronger, weak practice gets more output with the same problems.
06 · How to measure it in your own team
The studies disagree, so the useful move is a small measurement of your own. A plan that avoids the common traps:
- Baseline first. Record two to four weeks of current numbers before the rollout. Without a baseline, every later number is a feeling.
- Split by task type. New code in a fresh service, bug fixes in old code, migrations, tests and reviews behave differently. METR’s slowdown and Peng’s speed-up sit at opposite ends of this list.
- Pair speed with cost of change. Track cycle time together with rework within two weeks, review time per PR and defects found after release. More PRs with longer reviews and more rework is not a gain.
- Have a comparison. A team, a period or a set of tasks without the tool. Treat self-reports as a side signal: METR’s 40-point overestimate is the reason.
- Re-measure after several hundred hours. Learning takes time, so a first-month number can mislead in either direction.
Measurement works best next to practice that keeps the output in check. On my current projects we use an AI-first development process: written specs, test-driven development, and coding agents supervised under repository rules and release gates. On StroyIntellekt (strintel.ru), an AI system that checks construction cost documentation, about 2,000 automated tests check the code. In AgenticCRM (aigentos.tech), a chat-first agentic CRM, a CI step admits new tests only after a human confirms them, so the test suite stays a human decision. The agent writes code; tests and gates decide whether it is correct. That is what DORA’s “amplifier” looks like day to day.

07 · Which number to bring to leadership
When someone quotes a figure, ask what was measured:
- “AI makes developers 55% faster.” One greenfield task, 95 developers, 2022. Useful for new code, weak for a mature codebase.
- “Teams complete 26% more tasks.” Field trials with nearly 5,000 developers. Strong design, wide uncertainty, tasks of different size; ask whether review and rework time were counted.
- “Adopters merge 24% more PRs.” Observational. Ask how adopters were compared with non-adopters.
- “AI slows experts by 19%.” Strong design, narrow setting, early-2025 tools. The follow-up shows the setting has changed.
- “Heavy users write 4–10× more code.” A comparison between people, not the effect of the tool.
- “80% of developers feel more productive.” Perception. Participants in a measured trial misjudged the effect by about 40 points.
A defensible line for a leadership deck in 2026: published studies range from 19% slower to 56% faster depending on task and measure; our own baseline-and-comparison measurement over the next quarter will show where our team sits. The guide to agent evals applies the same discipline to the agents you ship.
What does your team track today: PRs, cycle time, or something closer to delivered value?